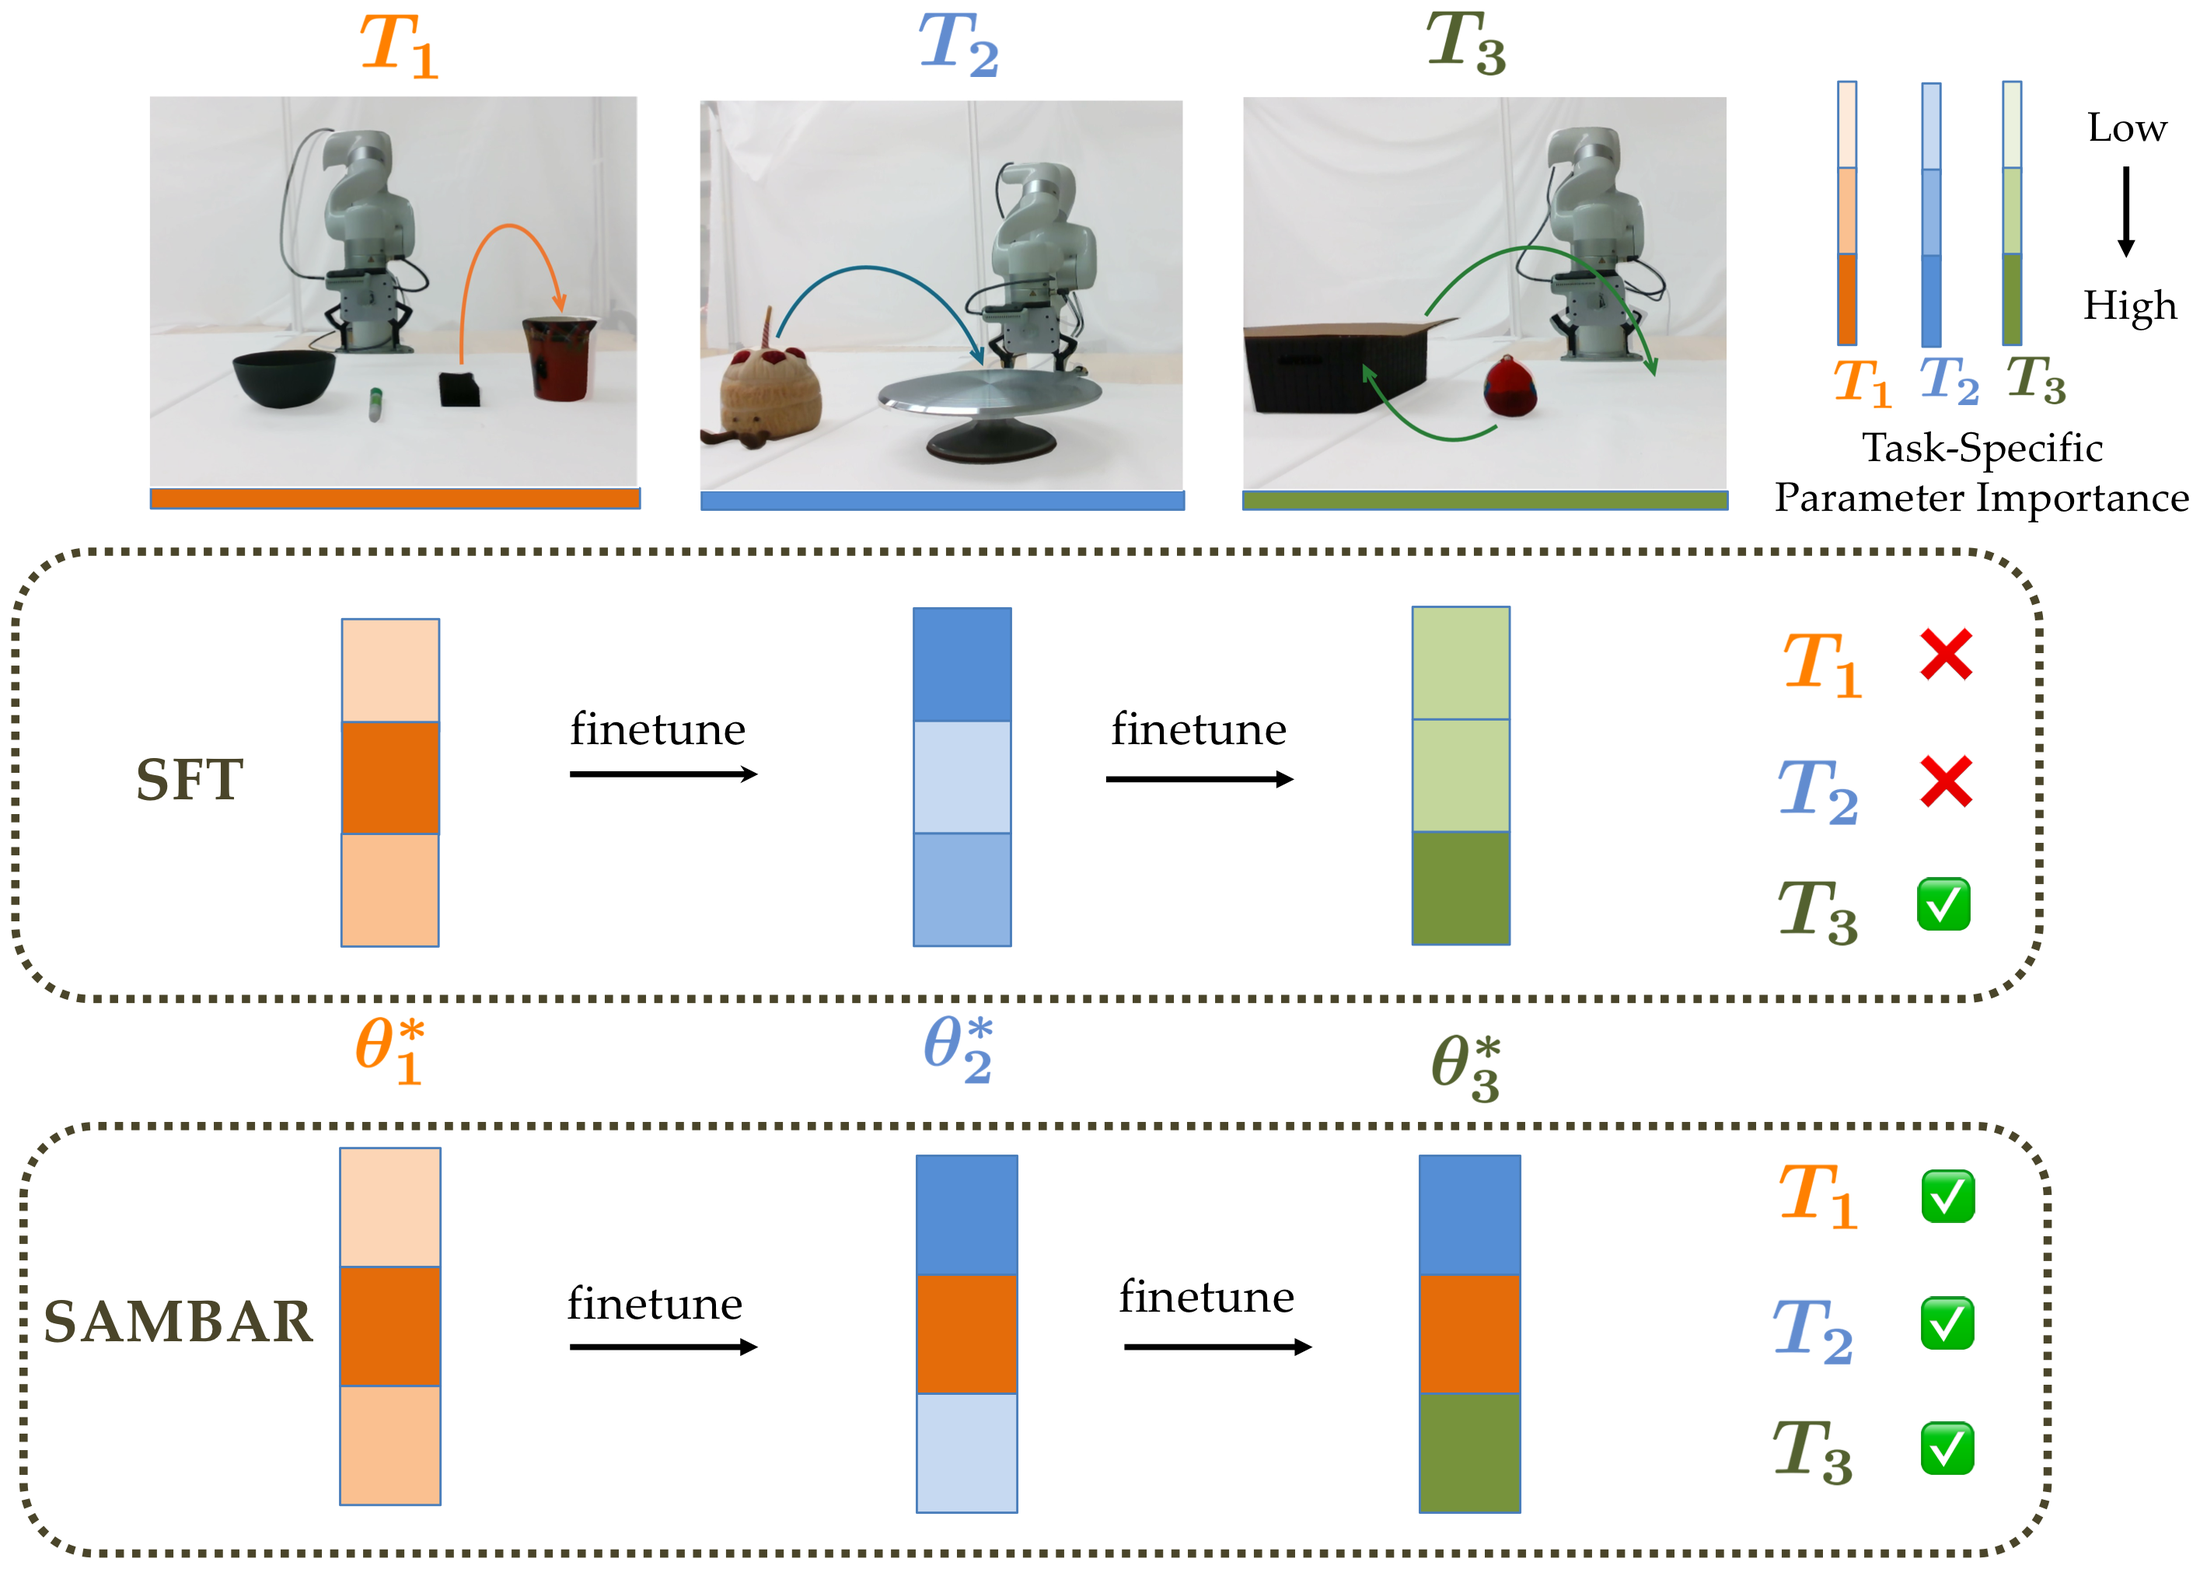
SFT and SAMBAR performance on an xArm7 manipulator. Videos play at 10× speed.
cake-on-cake-tray and then on remove-lid-and-place-bird, in sequence. SAMBAR remembers the pretraining task wheras SFT forgets. Both have similar performance on the both finetuning tasks.cake-on-cake-tray only, starting from the four pretraining tasks. SFT forgets the pretraining task: two-birds-in-binwhereas SAMBAR remembers all the pretraining tasks.remove-lid-and-place-bird only, starting from the four pretraining tasks. SFT forgets the pretraining task: eraser-in-mugwhereas SAMBAR remembers all the pretraining tasks.
| Method | Pretraining tasks ↑ | Pretrain SR ↑ | Finetune tasks ↑ | Weighted Avg SR ↑ | ||||
|---|---|---|---|---|---|---|---|---|
| bird-in-bin | two-birds-in-bin | eraser-in-mug | eraser-in-bowl | cake-on-cake-tray | remove-lid-and-place-bird | |||
| SFT | 5/5 | 5/5 | 5/5 | 3/5 | 90.0 | 4/5 | 3/5 | 83.3 |
| RETAIN ($\alpha=0.5$) | 5/5 | 5/5 | 4/5 | 4/5 | 90.0 | 5/5 | 0/5 | 76.7 |
| EWC | 5/5 | 5/5 | 5/5 | 5/5 | 100.0 | 4/5 | 2/5 | 86.7 |
| SAMBAR (ours) | 5/5 | 5/5 | 5/5 | 5/5 | 100.0 | 4/5 | 4/5 | 93.3 |
| Method | Pretraining tasks ↑ | Pretrain SR ↑ | Finetune SR ↑ | Weighted Avg SR ↑ | |||
|---|---|---|---|---|---|---|---|
| bird-in-bin | two-birds-in-bin | eraser-in-mug | eraser-in-bowl | ||||
| Finetune task: cake-on-cake-tray | |||||||
| SFT | 4/5 | 1/5 | 5/5 | 2/5 | 60.0 | 5/5 | 68.0 |
| RETAIN ($\alpha=0.5$) | 5/5 | 4/5 | 3/5 | 5/5 | 85.0 | 5/5 | 88.0 |
| EWC | 5/5 | 4/5 | 5/5 | 2/5 | 80.0 | 4/5 | 80.0 |
| SAMBAR (ours) | 5/5 | 5/5 | 5/5 | 5/5 | 100.0 | 5/5 | 100.0 |
| Finetune task: remove-lid-and-place-bird | |||||||
| SFT | 5/5 | 4/5 | 4/5 | 3/5 | 80.0 | 5/5 | 84.0 |
| RETAIN ($\alpha=0.5$) | 5/5 | 5/5 | 3/5 | 5/5 | 90.0 | 0/5 | 72.0 |
| EWC | 5/5 | 5/5 | 3/5 | 5/5 | 90.0 | 0/5 | 72.0 |
| SAMBAR (ours) | 5/5 | 5/5 | 5/5 | 5/5 | 100.0 | 4/5 | 96.0 |
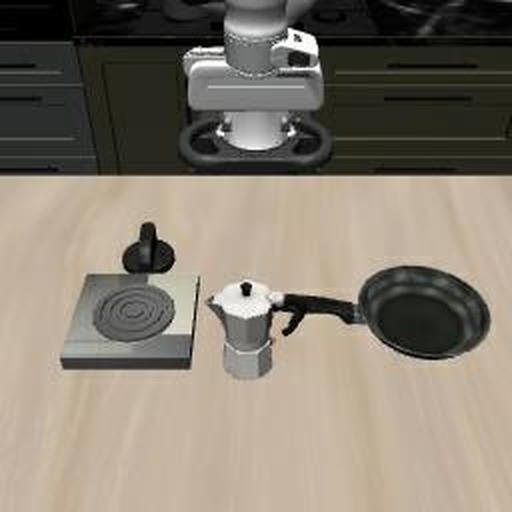
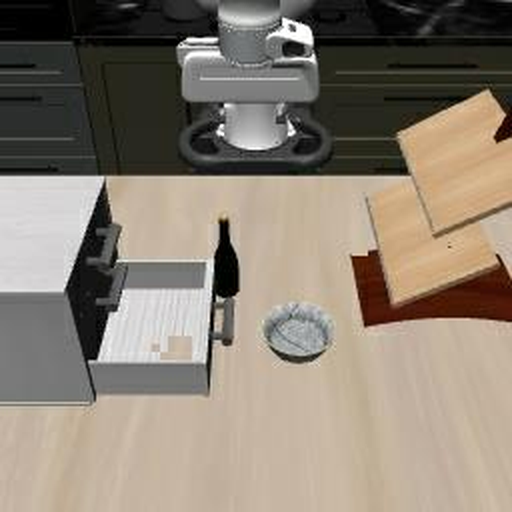
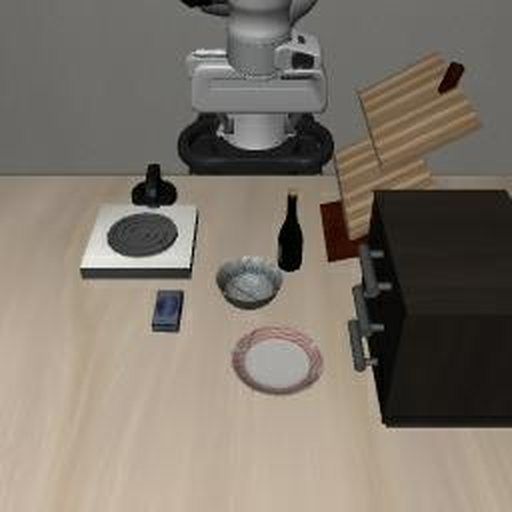
pot-on-stove, then
bowl-in-drawer, then bottle-on-rack, in the order shown. The first two are
long-horizon tasks; the third is a goal task.
pot-on-stove 0.0% of
the time after learning the two later tasks, while SAMBAR still performs it 84.0% of the time.
pot-on-stove after finetuning on two more tasks; SAMBAR holds 84.0% and leads Weighted Avg SR at 87.4% against 56.7% for the best baseline.| Method | Pretrain SR ↑ | Success on each newly learned task ↑ | Weighted Avg SR ↑ | ||
|---|---|---|---|---|---|
| pot-on-stove | bowl-in-drawer | bottle-on-rack | |||
| Co-Training | 95.4 ±1.0 | 100.0 ±0.0 | 98.0 ±5.6 | 88.0 ±13.6 | 95.4 |
| SFT | 12.9 ±1.9 | 0.0 ±0.0 | 60.0 ±21.5 | 84.0 ±11.1 | 15.9 |
| RETAIN | 17.4 ±0.7 | 0.0 ±0.0 | 68.0 ±16.2 | 96.0 ±6.8 | 20.6 |
| LoRA | 45.4 ±1.3 | 0.0 ±0.0 | 18.0 ±13.6 | 92.0 ±10.4 | 44.6 |
| EWC | 0.0 ±0.0 | 0.0 ±0.0 | 0.0 ±0.0 | 100.0 ±0.0 | 2.9 |
| L2 | 58.3 ±2.6 | 0.0 ±0.0 | 42.0 ±34.5 | 80.0 ±24.8 | 56.7 |
| Simple Recipe Works | 44.4 ±3.2 | 0.0 ±0.0 | 36.0 ±14.2 | 90.0 ±8.8 | 44.2 |
| SAMBAR w/o importance | 89.8 ±0.8 | 0.0 ±0.0 | 0.0 ±0.0 | 4.0 ±6.8 | 82.2 |
| SAMBAR (ours) | 88.2 ±2.3 | 84.0 ±6.8 | 70.0 ±15.2 | 82.0 ±16.2 | 87.4 |
| Method | Pretrain SR ↑ | Finetune SR ↑ | Weighted Avg SR ↑ |
|---|---|---|---|
| Finetune task: pot-on-stove | |||
| Pretrained (no finetuning) | 93.9 ±1.4 | 6.0 ±16.7 | – |
| Co-Training | 93.8 ±1.3 | 94.0 ±6.8 | 93.8 |
| SFT | 56.1 ±2.6 | 96.0 ±6.8 | 57.3 |
| RETAIN | 66.5 ±2.1 | 94.0 ±11.1 | 67.3 |
| LoRA | 75.4 ±1.8 | 100.0 ±0.0 | 76.2 |
| EWC | 47.1 ±1.4 | 96.0 ±11.1 | 48.6 |
| L2 | 71.5 ±2.2 | 74.0 ±16.7 | 71.6 |
| Simple Recipe Works | 84.0 ±1.3 | 86.0 ±16.7 | 84.0 |
| SAMBAR w/o importance | 91.8 ±1.4 | 4.0 ±6.8 | 89.1 |
| SAMBAR (ours) | 89.7 ±1.7 | 86.0 ±18.8 | 89.6 |
| Finetune task: bowl-in-drawer | |||
| Pretrained (no finetuning) | 93.9 ±1.4 | 0.0 ±0.0 | – |
| Co-Training | 93.1 ±1.7 | 100.0 ±0.0 | 93.3 |
| SFT | 23.1 ±1.4 | 100.0 ±0.0 | 25.4 |
| RETAIN | 27.4 ±1.8 | 96.0 ±6.8 | 29.5 |
| LoRA | 74.0 ±3.0 | 100.0 ±0.0 | 74.8 |
| EWC | 19.6 ±0.9 | 90.0 ±12.4 | 21.7 |
| L2 | 64.9 ±2.3 | 78.0 ±16.2 | 65.3 |
| Simple Recipe Works | 74.1 ±1.2 | 92.0 ±10.4 | 74.5 |
| SAMBAR w/o importance | 90.6 ±1.9 | 38.0 ±30.9 | 89.0 |
| SAMBAR (ours) | 91.8 ±1.2 | 96.0 ±6.8 | 91.9 |
| Method | Pretrain SR ↑ | Finetune SR ↑ | Weighted Avg SR ↑ |
|---|---|---|---|
| Finetune task: pot-on-stove | |||
| Pretrained (no finetuning) | 93.2 ±1.2 | 4.0 ±11.1 | – |
| SFT | 89.0 ±0.9 | 100.0 ±0.0 | 89.1 |
| RETAIN | 89.7 ±1.2 | 100.0 ±0.0 | 89.8 |
| LoRA | 88.1 ±0.6 | 100.0 ±0.0 | 88.2 |
| EWC | 89.5 ±1.4 | 100.0 ±0.0 | 89.6 |
| L2 | 84.8 ±0.7 | 84.0 ±11.1 | 84.8 |
| SAMBAR w/o importance | 89.7 ±1.4 | 56.0 ±32.4 | 89.5 |
| SAMBAR (ours) | 91.9 ±0.9 | 92.0 ±13.6 | 91.9 |
| Finetune task: items-into-basket | |||
| Pretrained (no finetuning) | 93.2 ±1.2 | 0.0 ±0.0 | – |
| SFT | 93.2 ±1.5 | 100.0 ±0.0 | 93.3 |
| RETAIN | 93.3 ±2.1 | 96.0 ±11.1 | 93.4 |
| LoRA | 93.4 ±0.9 | 100.0 ±0.0 | 93.5 |
| EWC | 93.5 ±1.2 | 100.0 ±0.0 | 93.6 |
| L2 | 93.8 ±1.2 | 92.0 ±13.6 | 93.8 |
| SAMBAR w/o importance | 94.3 ±0.5 | 36.0 ±11.1 | 93.8 |
| SAMBAR (ours) | 94.3 ±1.3 | 100.0 ±0.0 | 94.4 |
| Finetune task: mugs-on-plates | |||
| Pretrained (no finetuning) | 93.2 ±1.2 | 0.0 ±0.0 | – |
| SFT | 80.7 ±2.0 | 96.0 ±11.1 | 80.8 |
| RETAIN | 85.4 ±1.1 | 88.0 ±22.2 | 85.5 |
| LoRA | 91.9 ±1.3 | 100.0 ±0.0 | 91.9 |
| EWC | 78.8 ±0.8 | 96.0 ±11.1 | 78.9 |
| L2 | 86.1 ±0.6 | 80.0 ±30.4 | 86.0 |
| SAMBAR w/o importance | 93.2 ±1.2 | 76.0 ±20.8 | 93.1 |
| SAMBAR (ours) | 90.7 ±1.1 | 92.0 ±13.6 | 90.8 |
This work is supported by the National Science Foundation, under grants ECCS-2438314 CAREER Award, CNS-2529645. This work was also supported in part by an Office of Naval Research (ONR) Young Investigator Program (YIP) award. This research was made possible by GPU resources provided via the NVIDIA Academic Grant.
@article{shrivastava2026sambar,
  title   = {SAMBAR: Selective Anchoring via Method of Multipliers for Balanced
             Knowledge Acquisition and Retention in Vision-Language-Action Models},
  author  = {Shrivastava, Aayushi and Zhou, Xunlan and Zhao, Hongrui and
             Chen, Ziyu and Mehr, Negar},
  journal = {arXiv preprint arXiv:2609.32108},
  year    = {2026}
}